
知识库/第三方知识库
API 文件库
FastGPT API 文件库功能介绍和使用方式
背景
目前 FastGPT 支持本地文件导入,但很多企业自身已经建设了外部文档库。若将文件重复上传一遍,会造成二次存储且不便统一维护。因此 FastGPT 提供了 API 文件库机制,可通过标准化 API 接口按需拉取已有文档库中的文件。
只需按照 FastGPT 的 API 文件库规范实现对应文件接口,并在创建知识库时填入服务地址与鉴权凭证,即可直接在页面中浏览外部文件树并选择性导入。
如何使用 API 文件库
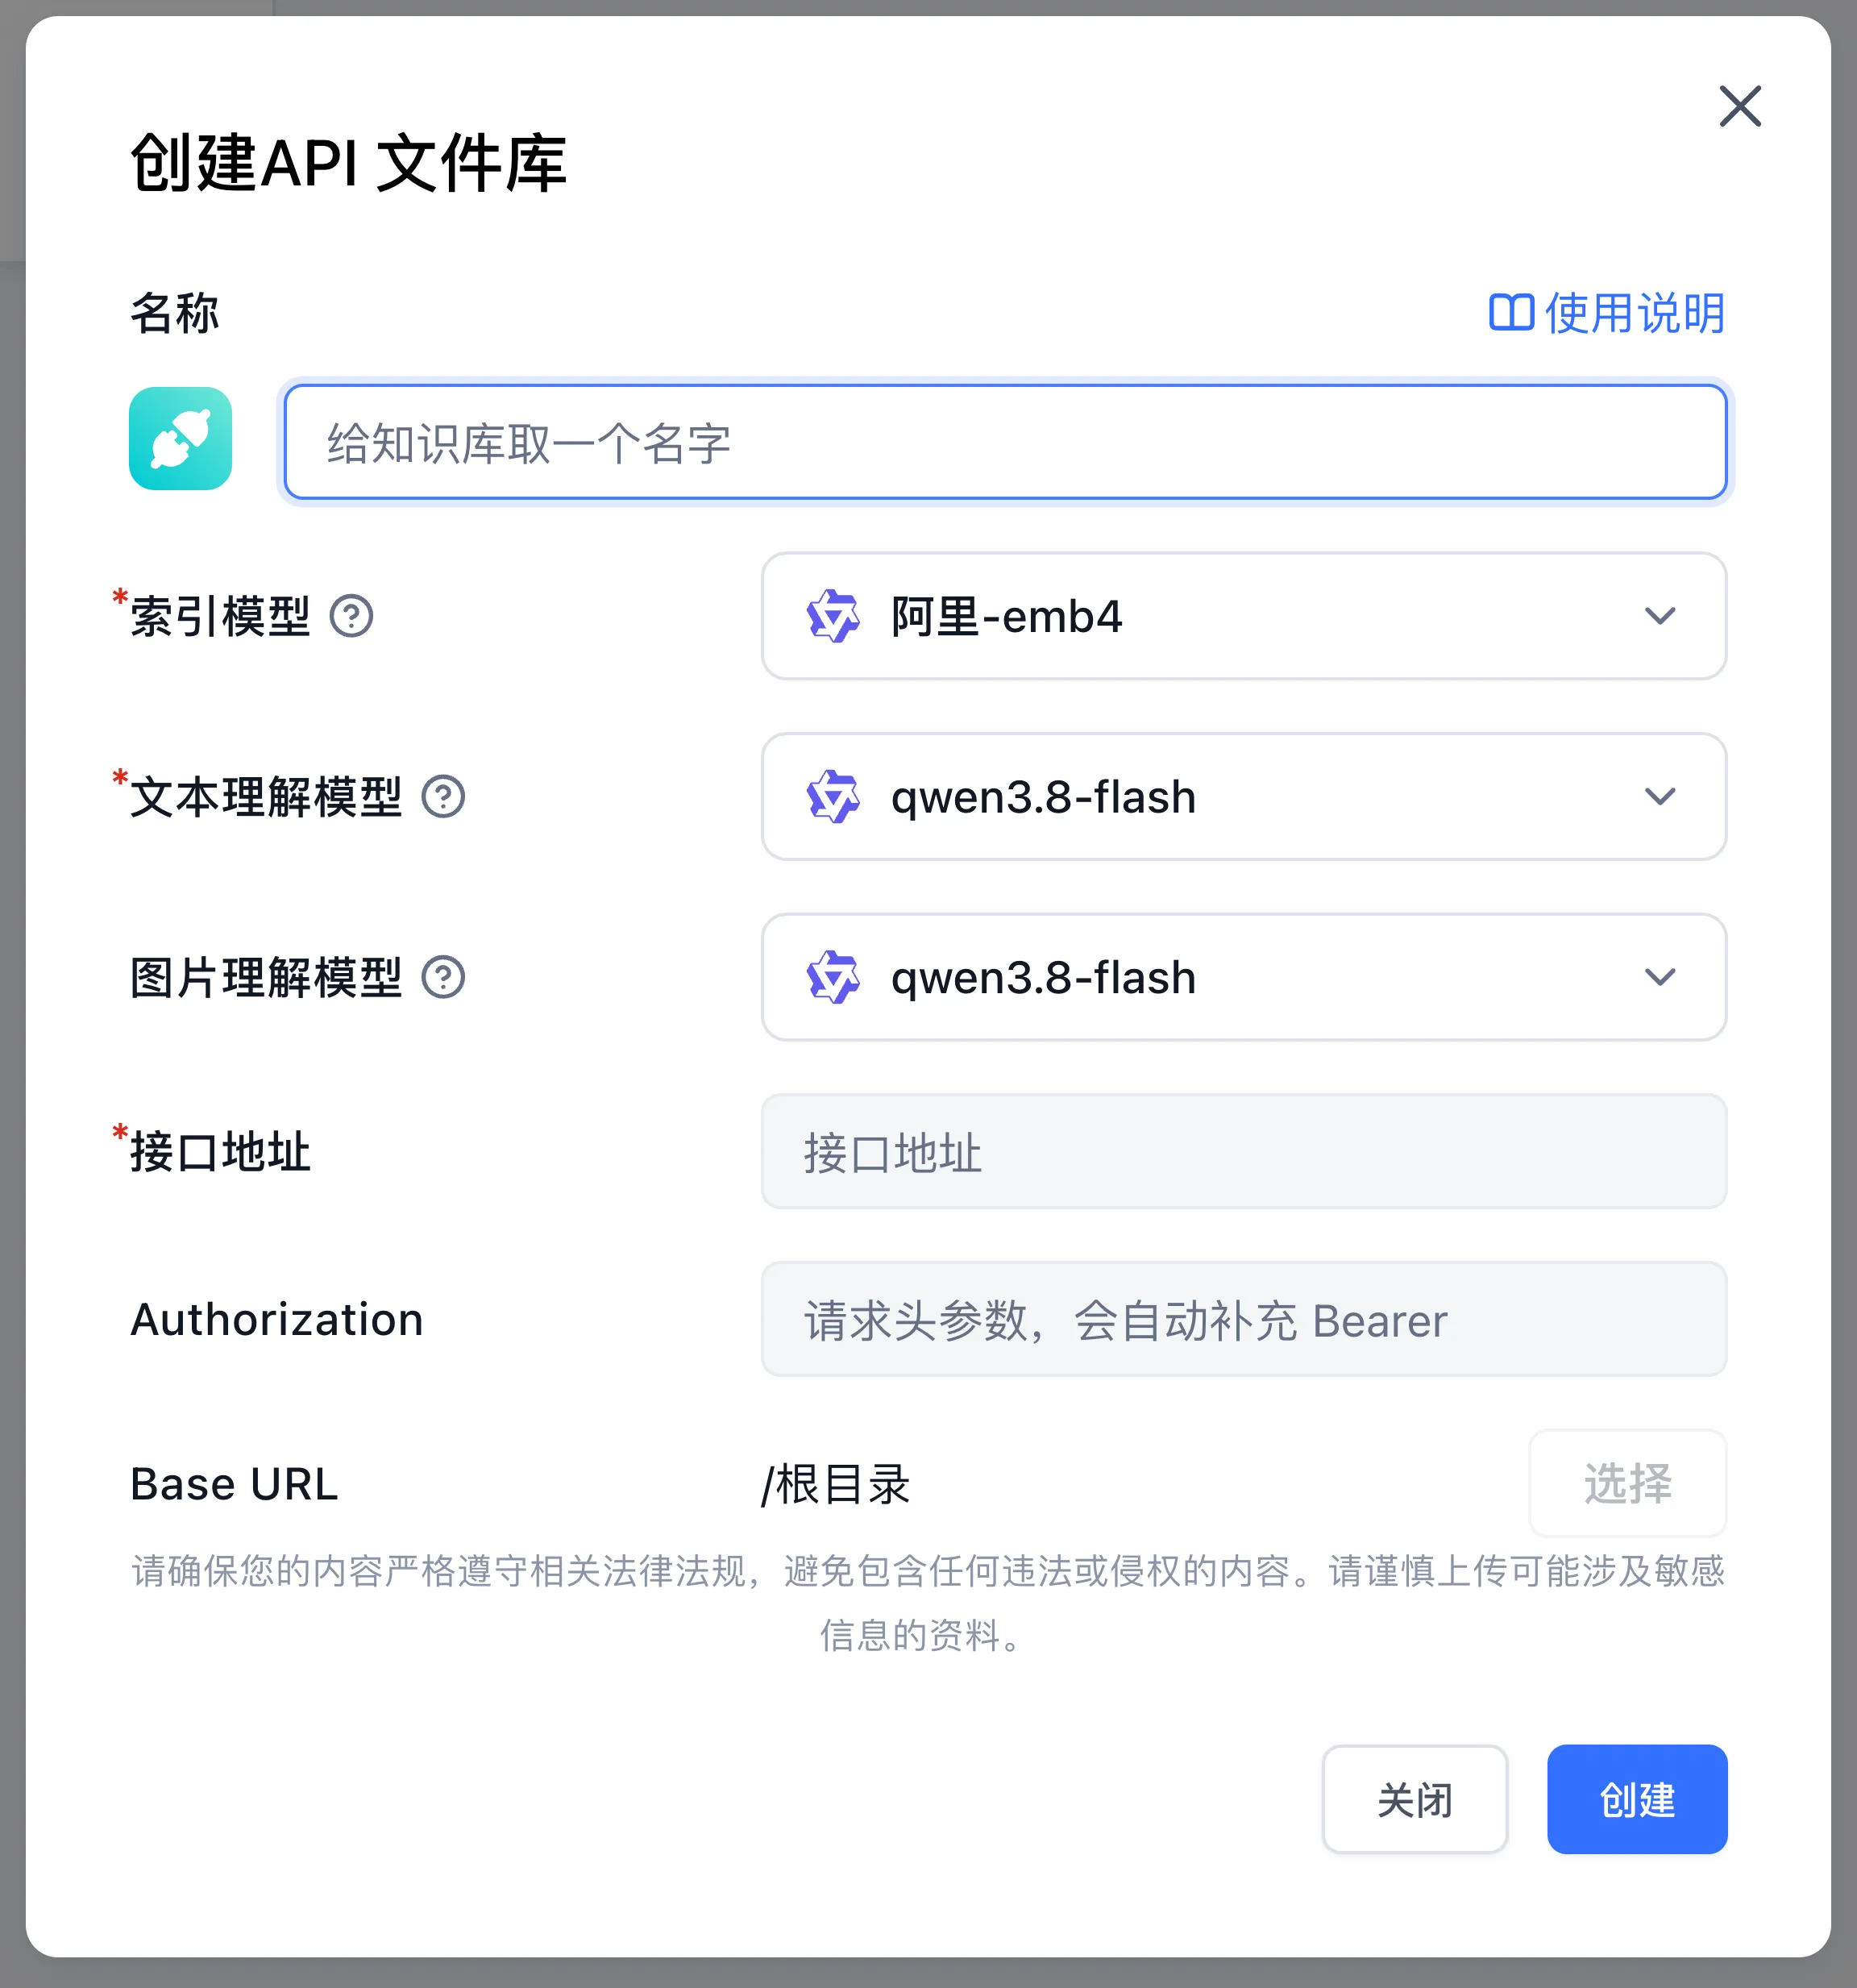
进入 知识库 → 新建 → 第三方知识库 → API 文件库,配置服务连接参数。只要提供的接口符合下方规范,系统即可自动获取并展示文件列表供选择性导入。
弹窗界面字段与接口参数的对应关系如下:
| 界面字段名 | 接口配置字段 | 说明 |
|---|---|---|
| 接口地址 | baseURL | 外部文件服务接口的根地址(如 https://files.example.com/api) |
| Authorization | authorization | 身份验证凭证,系统请求时会自动补充 Bearer 前缀(即发送 Authorization: Bearer <token>) |
| Base URL | basePath | 可选,文件树起始根目录;填写完前两项后点击右侧 选择 从远端目录树中选取 |
接口规范
接口响应格式:
type ResponseType = {
  success: boolean;
  message: string;
  data: any;
}
数据类型:
// 文件列表中,单项的文件类型
type FileListItem = {
  id: string;
  parentId: string | null;
  name: string;
  type: 'file' | 'folder';
  updateTime: Date;
  createTime: Date;
  hasChild?: boolean; // 可选,是否有子节点,默认 folder 类型为 true
}
1. 获取文件树
- parentId - 父级 id,可选。如果不传或传 null,则使用配置的 basePath 作为根目录
- searchKey - 检索词,可选
curl --location --request POST '{{baseURL}}/v1/file/list' \
--header 'Authorization: Bearer {{authorization}}' \
--header 'Content-Type: application/json' \
--data-raw '{
    "parentId": null,
    "searchKey": ""
}'
{
"success": true,
"message": "",
"data": [
{
"id": "xxxx",
"parentId": "xxxx",
"type": "file",
"name":"test.json",
"updateTime":"2024-11-26T03:05:24.759Z",
"createTime":"2024-11-26T03:05:24.759Z",
"hasChild": false
}
]
}2. 获取单个文件内容(文本内容或访问链接)
curl --location --request GET '{{baseURL}}/v1/file/content?id=xx' \
--header 'Authorization: Bearer {{authorization}}'
{
"success": true,
"message": "",
"data": {
"title": "文档标题",
"content": "FastGPT 是一个基于 LLM 大语言模型的知识库问答系统,提供开箱即用的数据处理、模型调用等能力。同时可以通过 Flow 可视化进行工作流编排,从而实现复杂的问答场景!\n"
}
}- title - 文件标题,可选。用于显示文件名称;未提供时,系统依次按下载响应的文件名、
/v1/file/detail返回的name、previewUrl路径中的文件名、随机 ID 回退生成。 - content - 文件的文本内容,可选。直接返回文件的完整文本内容,系统会直接使用该内容进行索引和检索。
- previewUrl - 文件的访问链接,可选。提供一个可访问的文件 URL,系统会自动请求该地址下载文件并提取内容。支持各种文件格式(如 PDF、Word、Markdown 等)。
重要说明:
content和previewUrl二选一返回,必须至少返回其中一个,否则会报错。- 如果同时返回
content和previewUrl,则content优先级更高,系统会直接使用content的内容。 - 返回
previewUrl时,系统会访问该链接进行文档内容读取和解析,并会缓存解析结果以提高性能。
3. 获取文件阅读链接(用于查看原文)
id 为文件的 id。
curl --location --request GET '{{baseURL}}/v1/file/read?id=xx' \
--header 'Authorization: Bearer {{authorization}}'
{
"success": true,
"message": "",
"data": {
"url": "xxxx"
}
}- url - 文件访问链接,拿到后会自动打开。
4. 获取文件详情
id 为文件的 id。
curl --location --request GET '{{baseURL}}/v1/file/detail?id=xx' \
--header 'Authorization: Bearer {{authorization}}'
{
"success": true,
"message": "",
"data": {
"id": "xxxx",
"name": "test.json",
"parentId": "xxxx",
"type": "file",
"updateTime": "2024-11-26T03:05:24.759Z",
"createTime": "2024-11-26T03:05:24.759Z"
}
}- id - 文件 id
- name - 文件名称
- parentId - 父级 id,null 表示根目录
- type - 文件类型,file 或 folder
- updateTime - 更新时间
- createTime - 创建时间
在 GitHub 上编辑
文件更新时间